


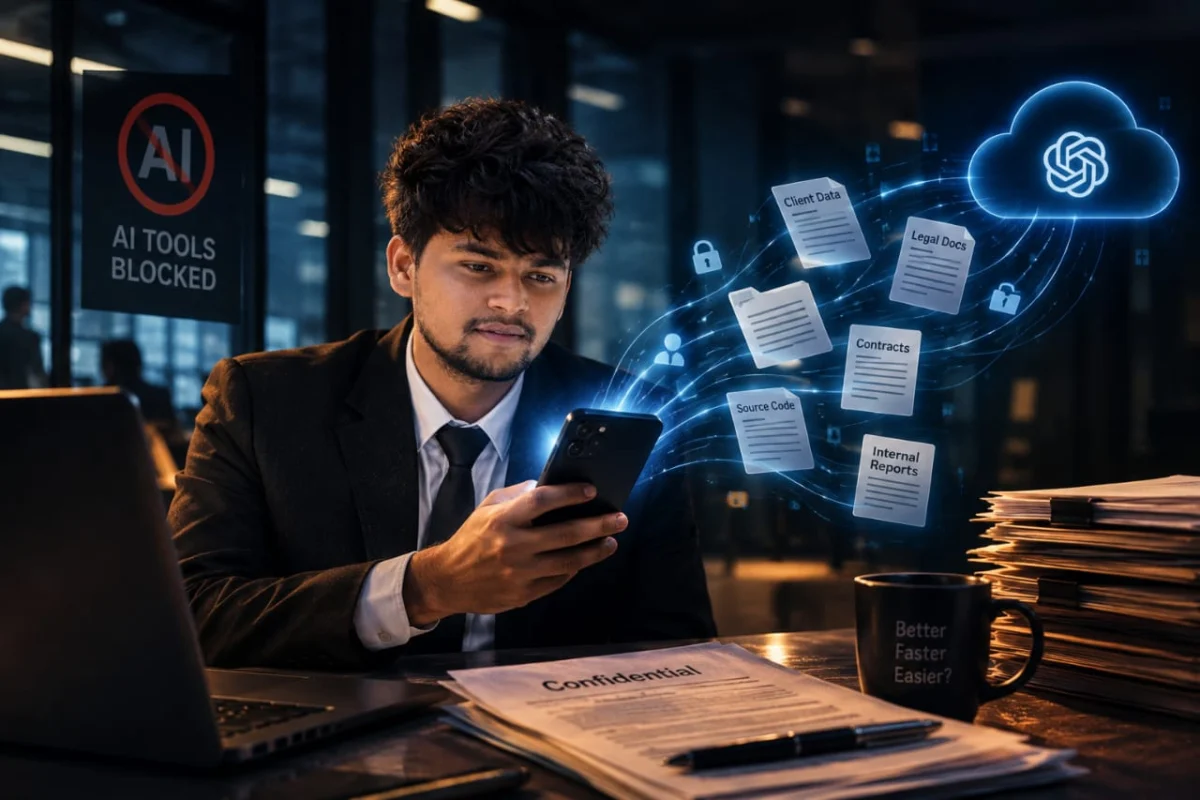
It is 1:45 AM in a corporate office, and a junior associate is staring blankly at a screen, trying desperately to finish a 110-page legal agreement that must be finalized and ready for review by 8:00 AM. The office coffee has long since gone cold, and after hours of reading the exact same dense terminology over and over again, even basic, straightforward clauses are beginning to blur into incomprehensible jargon.
There is still a mountain of work left to get through, and the window of time is rapidly closing.
Looking for any lifeline available, the associate pulls out a personal smartphone, opens a free artificial intelligence chatbot, and copies three complex clauses directly from the proprietary agreement. Within mere seconds, the digital tool generates a concise, readable summary. The immediate bottleneck clears, the workload becomes slightly more manageable, and the tired associate presses forward to the next urgent task on the list.
Yet, this routine efficiency masks a significant underlying compliance failure. The law firm in question has already instituted a strict ban on public artificial intelligence tools. Its corporate network computers actively block access to these external websites, and management has repeatedly warned all personnel against using unapproved platforms for professional duties. Despite these firm-wide restrictions, however, the associate has seamlessly bypassed the internal network firewall by routing the traffic through a personal mobile device and a private cellular connection.
The firm’s enterprise security system may show that its perimeter restrictions are functioning as designed, successfully blocking unauthorized traffic across corporate computers. But that system cannot monitor what is being transmitted through an isolated personal connection.
This scenario illustrates the quiet, pervasive entry point of Shadow AI into the modern workplace. The employee may harbor no malicious intent to expose sensitive corporate or client information, driven instead by the simple, human desire to survive an overwhelming deadline. Nevertheless, confidential data has slipped past organizational boundaries and moved outside corporate control, exposing a critical vulnerability that companies everywhere must confront: If employees continue to find clever workarounds to utilize artificial intelligence despite explicit workplace bans, is merely blocking access truly enough to protect the enterprise?
Understanding the Shadow AI Problem
Shadow AI broadly describes the utilization of artificial intelligence applications, platforms, and services by employees without the explicit knowledge, review, or approval of their organization’s IT and compliance departments. These unauthorized tools frequently encompass public-facing chatbots, automated writing assistants, browser extensions, specialized coding assistants, and automated meeting transcription applications.
Crucially, the challenge extends far beyond the specific software application an employee chooses to open. The core risk lies in the exact nature of the information being fed into these external systems.
An employee under pressure might upload a confidential client document to generate a quick executive summary, input proprietary financial data to accelerate the drafting of a quarterly report, or paste a sensitive section of source code into an online utility to isolate and fix a stubborn programming error. From the perspective of the individual worker, these actions appear entirely harmless, viewed merely as pragmatic shortcuts to boost productivity. Yet, the organization itself may have zero visibility into where that transmitted data ultimately travels, how long and in what format it is stored, or what security measures govern its handling after the task is completed.
In response to these emerging vulnerabilities, a large number of corporations have moved quickly to restrict or outright block public AI platforms. Their underlying concerns are entirely valid and understandable. Confidential business information, proprietary customer records, and sensitive legal documentation should never be shared casually with external web services that have not undergone rigorous security and privacy assessments.
However, implementing a technical restriction does not automatically translate to a shift in employee behavior. If a corporation aggressively blocks an AI website on its local network but maintains the exact same heavy workloads and tight deadlines, the fundamental motivations driving workers toward artificial intelligence do not vanish. Instead, frustrated employees simply pivot toward alternative access routes.
This divergence marks the genesis of the true enterprise risk. A company may successfully disable a specific application on its office desktop computers while remaining completely oblivious to the fact that its workforce is actively utilizing the exact same platforms via personal smartphones, private home accounts, or external cellular hotspots.
Banning AI effectively limits official, monitored corporate systems from interacting with external models, but it does not stop the utilization itself. In many cases, it merely drives the activity further underground, completely out of the sight and control of organizational oversight.
The integration of artificial intelligence into daily routines is currently expanding at a pace that far outstrips the ability of most organizations to formulate comprehensive internal policies and deploy native enterprise solutions. Data compiled in the 2024 Work Trend Index published by Microsoft and LinkedIn revealed that roughly 75 percent of global knowledge workers actively utilize artificial intelligence in their professional tasks. Among that large cohort of active users, an overwhelming 78 percent reported bringing their own preferred AI tools directly to the workplace—a phenomenon widely characterized as Bring Your Own AI, or BYOAI.
This trend mirrors broader, established shifts in enterprise technology adoption. Research conducted by Gartner indicates that more than 41 percent of modern employees routinely acquire, modify, or implement technology solutions entirely outside the visibility and control of their internal IT departments.
These figures highlight a fundamental reality: modern workers are no longer waiting for their employers to formally introduce every technological innovation they wish to leverage. However, these statistics must be interpreted carefully. While they clearly illustrate widespread workplace adoption and a heavy reliance on personal productivity tools, they do not imply that corporate bans are the direct catalyst for their use.
The driving forces behind this behavior are intensely practical. A legal professional wants to digest a lengthy brief in a fraction of the time; a market researcher needs to synthesize vast quantities of disorganized data; a software engineer requires immediate assistance debugging complex code; and an administrative employee drafting a high-stakes presentation seeks an initial structural outline.
In every single instance, the underlying objective is identical: the employee is striving to save valuable time and execute their responsibilities with greater efficiency.
This operational reality does not render every unauthorized use of technology acceptable. Employees retain an ongoing professional responsibility to adhere strictly to workplace governance and safeguard confidential data entrusted to their care. At the same time, organizations must look beyond punitive measures to understand the genuine operational pressures driving their staff toward unapproved solutions.
A corporate policy that consists solely of a blanket prohibition—effectively telling workers not to use artificial intelligence—fails to address the daily challenges professionals face on the ground. It leaves critical questions unanswered: Which specific tools are permissible? What categories of information are safe to share? What protocols should be followed when an approved corporate system fails to handle a complex task?
When organizations leave these practical questions hanging, employees inevitably begin making independent judgment calls. That exact disconnect is how corporate technology policies drift away from actual, everyday workplace behavior.
The Samsung Incident: When Workplace Use Becomes a Data Risk
The theoretical dangers associated with unauthorized technology use materialized vividly in April 2023, when technology giant Samsung Electronics reportedly confronted a series of internal security breaches involving staff members entering sensitive corporate information into generative AI platforms like ChatGPT. According to subsequent reports, employees utilized the public tool to assist with work-related tasks, inadvertently pasting proprietary semiconductor source code and confidential internal meeting notes into the external system.
This high-profile incident served as a stark wake-up call for corporations worldwide, demonstrating conclusively that sensitive intellectual property can leave an organization through routine, everyday professional activities. An employee does not need to compromise a firewall or harbor malicious intent to harm an employer; simply copying and pasting internal operational data into an external chatbot can trigger a severe security exposure.
Samsung’s subsequent response involved implementing strict limitations on the use of generative AI across its operations. While the incident clearly illustrated why major enterprises grew deeply alarmed by public AI platforms, it also highlighted a complex secondary challenge: managing the human element of technology use when workers seek productivity enhancements outside official channels.
Furthermore, when corporate data is entered into an external artificial intelligence service, organizations must grapple with the varying data handling practices of different platform providers.
Different AI developers enforce vastly disparate terms of service and default privacy settings. Certain public services reserve the right to incorporate submitted user content into future model training datasets under specific conditions, whereas others maintain strict enterprise agreements that feature robust data-retention limits and explicit non-training guarantees. Assuming that every public AI service handles user prompts with identical privacy standards represents a hazardous gamble.
The overarching concern is that employees utilizing personal accounts on external platforms rarely possess a clear understanding of which specific terms apply to their inputs. Consequently, the organization operates entirely blind, lacking formal contracts, security reviews, or management controls to mitigate the resulting risk.
What Is Actually at Risk?
For corporations, financial institutions, and legal practices alike, the proliferation of Shadow AI extends far beyond a standard information technology compliance hurdle. Unchecked external usage directly threatens data confidentiality, legal compliance obligations, customer trust, and core business interests across several distinct categories.
Legal professionals handle sensitive information as a matter of course. This category encompasses confidential client communications, unexecuted draft agreements, evolving litigation strategies, personal records, and proprietary documents that have not entered the public domain. Uploading such sensitive material to an external AI service without explicit clearance introduces immediate confidentiality vulnerabilities.
Nevertheless, legal experts draw an important distinction between general confidentiality obligations and the strict boundaries of attorney-client privilege. Transmitting privileged information to a third-party service does not automatically waive privilege in every legal jurisdiction or factual context. The ultimate legal determination depends heavily on local statutes, the precise circumstances surrounding the disclosure, the specific service provider’s data access rights, and the proactive steps taken by the firm to preserve confidentiality.
Even in scenarios where formal privilege is not immediately destroyed, sharing client data without proper technical safeguards can violate professional ethics, industry regulations, and contractual agreements. For a modern law firm, evaluating an AI tool must involve more than assessing the quality of its generated output; it requires verifying whether the underlying data is legally permitted to leave the firm’s controlled environment.
Data protection risks escalate exponentially when employees inadvertently introduce personal information into unapproved artificial intelligence platforms.
A routine business document may easily contain a client’s full name, residential address, banking details, national identification numbers, or other sensitive personal identifiers. If this information is transmitted to an external web service devoid of appropriate data protection safeguards, the organization may find itself facing severe regulatory scrutiny.
Legislative frameworks worldwide reflect the gravity of these exposures. Under India’s Digital Personal Data Protection Act, 2023, significant financial penalties are established for statutory failures. Specifically, the legislation outlines penalties of up to 250 crore rupees for failing to implement reasonable security safeguards capable of preventing personal data breaches. While an isolated instance of an employee querying a chatbot does not automatically trigger maximum statutory fines, organizations must navigate these legal exposures based on the specific facts and circumstances of any data disclosure.
Similarly, within the European Union, severe infringements of the General Data Protection Regulation (GDPR) can attract administrative fines reaching up to 20 million euros, or up to 4 percent of an enterprise’s total worldwide annual turnover from the preceding financial year, whichever metric is higher.
These regulatory figures underscore why modern enterprises must treat data stewardship with absolute seriousness. Beyond direct financial penalties, a compromised dataset inflicts severe collateral damage on customer trust, business partnerships, and overall corporate reputation. Broad industry research, such as IBM’s 2023 Cost of a Data Breach Report which estimated the global average cost of a breach at $4.45 million, illustrates the immense financial fallout security incidents can generate across an organization.
Beyond personal data and client confidentiality, companies heavily rely on the protection of trade secrets to maintain a competitive advantage in the marketplace. This proprietary corpus frequently encompasses complex source code, innovative product designs, strategic pricing models, financial forecasting projections, customer databases, and upcoming expansion plans.
Maintaining the strict confidentiality of these assets is a foundational requirement for securing legal trade secret protection. If employees routinely input this proprietary material into public AI utilities without verifying the provider’s terms of service or corporate security parameters, the enterprise may severely weaken its legal standing. Specifically, courts may determine that the company failed to take reasonable steps to safeguard its own confidential information, thereby forfeiting trade secret protections.
While the exact legal standing varies depending on governing jurisdictions and specific circumstances, the underlying commercial risk remains straightforward: critical business intelligence meant to remain strictly internal is being transferred to external commercial entities without oversight or control.
Why Blanket Bans May Not Solve the Problem
At first glance, implementing a blanket block on artificial intelligence websites appears to be the most direct and effective administrative response. An enterprise can restrict network-level access, publish a rigid corporate policy, and issue stern warnings cautioning employees against utilizing unapproved platforms.
However, returning to the scenario of the exhausted junior associate highlights the fundamental flaw in this approach. Restricting a website on a corporate laptop does not physically prevent that same employee from opening the identical web address on a personal mobile phone. Furthermore, leveraging a personal cellular hotspot effortlessly routes network traffic around the corporate firewall entirely.
Management may look at internal network analytics and conclude that company systems are fully compliant with policy, remaining completely unaware of the extensive activity occurring outside those monitored parameters.
This dynamic creates a profound disconnect between merely controlling network access and genuinely controlling actual organizational use.
An enterprise that proactively provides approved, secure artificial intelligence tools maintains the ability to establish clear operational boundaries regarding user access, permitted data types, and required security baselines. Furthermore, it can audit and review usage patterns through appropriate technical controls.
Conversely, when employees are forced to rely on personal accounts and private devices to complete their daily assignments, the organization forfeits vital visibility. Leadership loses the ability to track which tools are actively deployed, what sensitive corporate information has been shared externally, or whether a data exposure incident has quietly occurred.
Acknowledging this reality does not imply that companies should grant unrestricted access to every available AI application. Certain high-risk operations must remain strictly prohibited, particularly in environments where sensitive information cannot be adequately protected. However, treating a simple access ban as a complete, self-contained solution ignores the practical realities driving employees toward these technologies.
The core challenge facing modern businesses is not simply whether to permit or prohibit artificial intelligence. Rather, it is whether existing corporate policies provide workers with safe, practical, and efficient mechanisms to execute their professional responsibilities.
A Practical Way Forward: From Bans to AI Governance
To navigate this complex landscape, organizations must implement governance frameworks that protect sensitive assets without ignoring the practical realities of modern workflows. Achieving this balance does not require opening the floodgates to unrestricted public AI; instead, it demands clear operational rules, appropriate technological alternatives, and safeguards precisely calibrated to the sensitivity of the data involved.
A primary strategy involves supplying approved enterprise-grade artificial intelligence tools. When employees turn to public platforms simply because they require assistance with routine tasks, organizations should evaluate deploying secure enterprise alternatives.
Enterprise-grade AI services frequently offer distinct contractual and technical protections, including strict limitations on data retention and formal commitments ensuring that customer inputs are never utilized for underlying model training. Certain commercial providers even offer Zero Data Retention configurations.
Nevertheless, organizations must carefully review actual service level agreements rather than assuming that an enterprise label or a marketing promise guarantees absolute privacy. Compliance teams must verify precisely what data is retained, what operational logs are generated, who maintains access permissions, and which security settings are enabled by default.
The ultimate objective is providing personnel with a reliable, efficient tool for daily operations, thereby removing the incentive to rely on vulnerable personal accounts or unapproved external services.
For specialized operations involving highly sensitive data—such as proprietary source code, confidential legal strategies, high-level client files, or classified business intelligence—organizations can deploy localized artificial intelligence models running entirely on internal infrastructure or within heavily controlled private environments.
Open-source model architectures, such as the Llama and Mistral model families, offer viable pathways for internal deployment, depending on the technological resources available to the enterprise. For ultra-sensitive workloads, completely disconnected or air-gapped hardware configurations can introduce an additional, impenetrable layer of physical security.
Even local deployments, however, are not inherently foolproof. Organizations must still manage access permissions, system patching, software updates, and the specific categories of data employees feed into the local model.
To prevent ambiguity, organizations must establish a transparent data classification system so that workers never have to guess whether a particular document is safe to share with an AI utility.
A functional approach involves categorizing organizational information into distinct tiers, such as public, internal, and confidential. Public information—encompassing published reports, press releases, and publicly available case law—can safely be utilized with approved public or enterprise AI tools. Internal information, including routine meeting notes and preliminary internal drafts, should be restricted strictly to AI tools vetted and approved under corporate policy. Confidential data, comprising client records, personal identification information, active contracts, source code, and merger and acquisition details, demands maximum protection, requiring either specialized restricted tools or explicit managerial approval prior to sharing.
This classification framework must remain intuitive and align seamlessly with pre-existing corporate confidentiality policies, with legal departments maintaining specialized restrictions for privileged communications and litigation materials.
To enforce these policies technically, organizations can implement Data Loss Prevention tools. DLP solutions assist enterprises in identifying, monitoring, and automatically blocking the transmission of sensitive information.
Modern DLP platforms can detect personal identification numbers, banking details, and proprietary keywords embedded within data streams heading toward external web services. Depending on the system configuration, the software can intercept the request, flag the activity for compliance review, or redact sensitive strings before the data reaches an external endpoint.
Because these security tools are not infallible—occasionally missing subtle disclosures or incorrectly flagging benign text—they must serve to reinforce, rather than replace, clear corporate policies and thorough employee training.
Finally, organizations must integrate their workforce directly into the governance process. Even a meticulously designed compliance framework will inevitably fail if employees lack a practical understanding of how to apply it within their daily routines.
Enterprises should clearly communicate which specific AI tools have earned formal approval, what categories of information must never be transmitted externally, when mandatory human review is required, and the exact protocol for requesting access to new software utilities.
Crucially, companies must also establish a transparent, non-punitive mechanism for reporting accidental data disclosures. When employees operate under a climate of fear, hesitant to report honest mistakes, organizations inevitably learn about security incidents far too late to mount an effective response.
At the same time, employees retain an unwavering professional duty to adhere to established safety guidelines. Providing practical technological alternatives does not absolve workers from their core responsibility to protect confidential data. Organizations require a balanced combination of clear operational expectations, modern tools, and fair accountability.
Shadow AI will not simply vanish from the modern workplace because an organization erects network blocks against specific websites. Employees continue to face unrelenting deadlines, daily administrative tasks, and complex workloads that demand efficiency. When approved enterprise tools are unavailable or overly cumbersome, human nature dictates that workers will seek out alternative paths to get their jobs done.
This reality presents a persistent governance challenge. Organizations may maintain strict written rules prohibiting unapproved technologies, but those policies alone cannot reveal where employees are actually leveraging artificial intelligence or what proprietary information is being shared along the way.
Addressing this challenge requires looking past prohibition and examining the fundamental reasons professionals reach for external tools. If a particular application demonstrably helps employees navigate routine tasks more effectively, the organization is challenged to provide a safe, compliant alternative while establishing clear boundaries regarding data sharing.
The core issue is not simply whether a workforce is following artificial intelligence policies, but whether those policies function effectively within the reality of how people actually perform their jobs. For organizations striving to manage Shadow AI, understanding its usage is an essential first step toward meaningful control.

Comments (0)